2026
Beyond Action Entropy: Quotient-Space Exploration for Genome-Scale Metabolic Model Repair
Xuan Gong*, Hanbo Huang*, Wenbin Dai*, Jing Wang, Lei Bai, Xiang Xiao, Weishu Zhao, Shiyu Liang# (* equal contribution, # corresponding author)
AgenticLS Workshop @ NeurIPS 2026 Oral
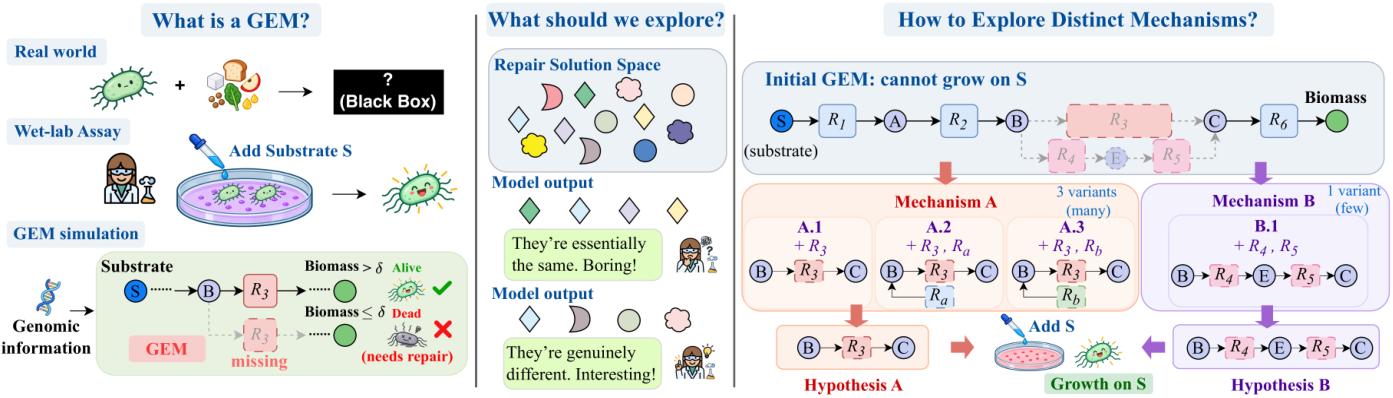
QuotientPO explores distinct biological mechanisms rather than equivalent surface edits, enabling more effective phenotype-supervised repair of genome-scale metabolic models.
Beyond Action Entropy: Quotient-Space Exploration for Genome-Scale Metabolic Model Repair
Xuan Gong*, Hanbo Huang*, Wenbin Dai*, Jing Wang, Lei Bai, Xiang Xiao, Weishu Zhao, Shiyu Liang# (* equal contribution, # corresponding author)
AgenticLS Workshop @ NeurIPS 2026 Oral
QuotientPO explores distinct biological mechanisms rather than equivalent surface edits, enabling more effective phenotype-supervised repair of genome-scale metabolic models.
REACT: Physically and Chemically Consistent Reconstruction of Marine Active Tracers
Wenbin Dai*, Hao Zheng*, Shiyu Liang*#, Chaofan Sun, Xueying Zhang, Hanbo Huang, Xuan Gong, Yiran Zhang, Enhui Liao (* equal contribution, # corresponding author)
NeurIPS 2026 · AI4Physics Workshop @ ICML 2026
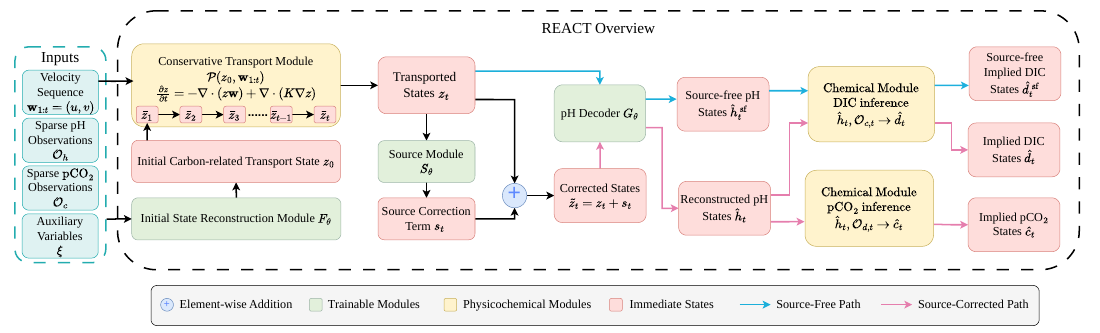
REACT reconstructs sea surface pH from sparse observations through a carbon-first framework that combines conservative transport, active source correction, and chemical decoding to preserve physical and carbonate-system consistency.
REACT: Physically and Chemically Consistent Reconstruction of Marine Active Tracers
Wenbin Dai*, Hao Zheng*, Shiyu Liang*#, Chaofan Sun, Xueying Zhang, Hanbo Huang, Xuan Gong, Yiran Zhang, Enhui Liao (* equal contribution, # corresponding author)
NeurIPS 2026 · AI4Physics Workshop @ ICML 2026
REACT reconstructs sea surface pH from sparse observations through a carbon-first framework that combines conservative transport, active source correction, and chemical decoding to preserve physical and carbonate-system consistency.
Reflection Anchors for Propagation-Aware Visual Retention in Long-Chain Multimodal Reasoning
Xuan Gong, Hanbo Huang, Hao Zheng, Yiran Zhang, Wenbin Dai, Weishu Zhao, Shiyu Liang# (# corresponding author)
NeurIPS 2026 · CompLearn Workshop @ ICML 2026
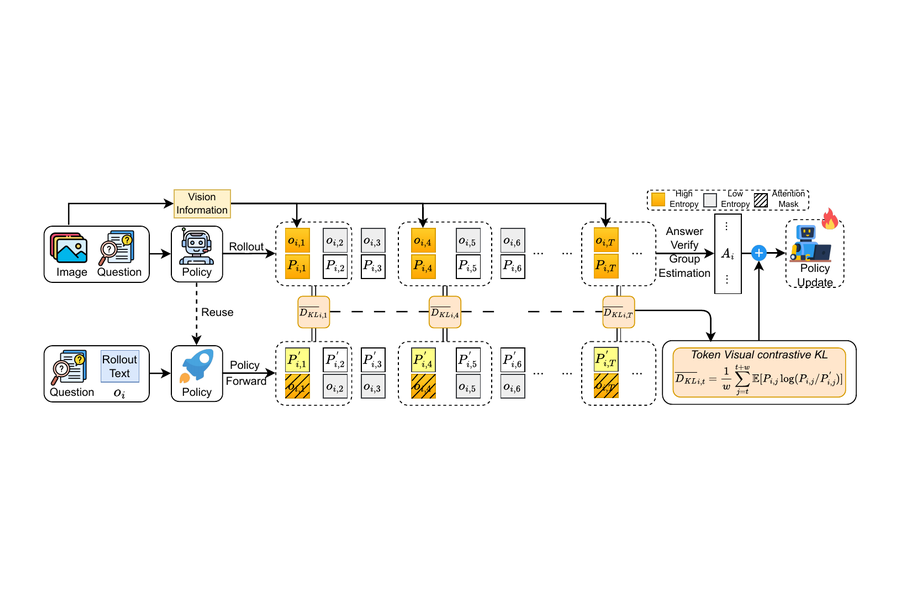
This work introduces reflection anchors for propagation-aware visual retention, targeting long-chain multimodal reasoning where visual evidence must remain reliable across extended inference.
Reflection Anchors for Propagation-Aware Visual Retention in Long-Chain Multimodal Reasoning
Xuan Gong, Hanbo Huang, Hao Zheng, Yiran Zhang, Wenbin Dai, Weishu Zhao, Shiyu Liang# (# corresponding author)
NeurIPS 2026 · CompLearn Workshop @ ICML 2026
This work introduces reflection anchors for propagation-aware visual retention, targeting long-chain multimodal reasoning where visual evidence must remain reliable across extended inference.
RLCracker: Evaluating the Worst-Case Vulnerability of LLM Watermarks with Adaptive RL Attacks
Hanbo Huang, Yiran Zhang, Hao Zheng, Xuan Gong, Yihan Li, Lin Liu, Zhuotao Liu, Shiyu Liang# (# corresponding author)
ICML 2026
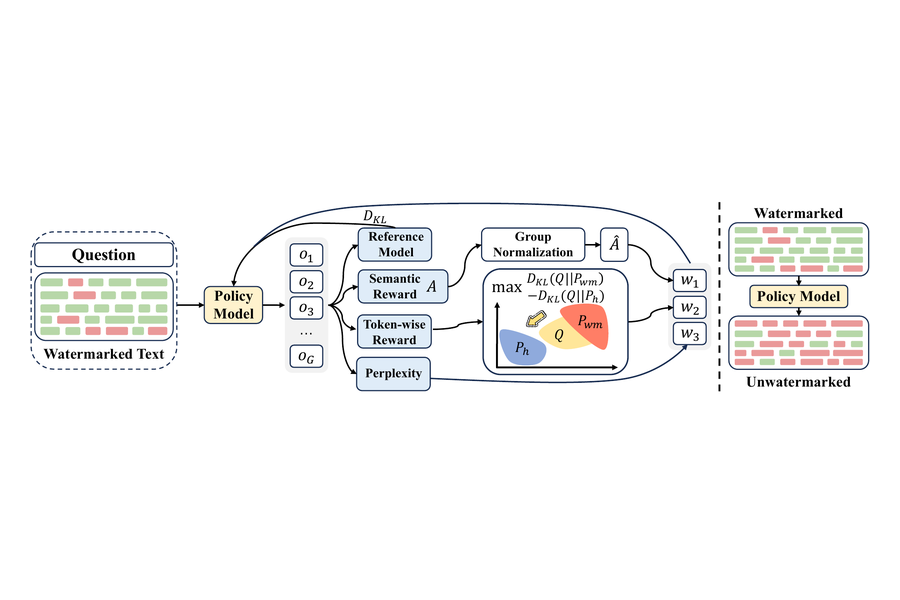
RLCracker studies adaptive reinforcement-learning attacks against LLM watermarks, exposing watermark vulnerabilities under learned black-box attack policies.
RLCracker: Evaluating the Worst-Case Vulnerability of LLM Watermarks with Adaptive RL Attacks
Hanbo Huang, Yiran Zhang, Hao Zheng, Xuan Gong, Yihan Li, Lin Liu, Zhuotao Liu, Shiyu Liang# (# corresponding author)
ICML 2026
RLCracker studies adaptive reinforcement-learning attacks against LLM watermarks, exposing watermark vulnerabilities under learned black-box attack policies.
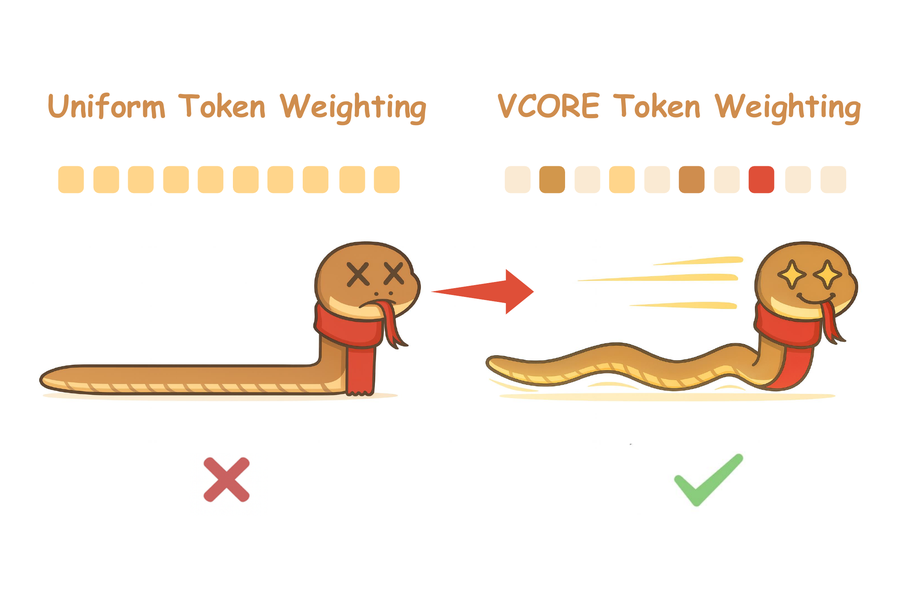
VCORE: Variance-Controlled Optimization-based Reweighting for Chain-of-Thought Supervision
Xuan Gong, Senmiao Wang, Hanbo Huang, Ruoyu Sun, Shiyu Liang# (# corresponding author)
ACL 2026 Main
VCORE introduces variance-controlled optimization-based reweighting for chain-of-thought supervision, improving how reasoning traces contribute to model training.
VCORE: Variance-Controlled Optimization-based Reweighting for Chain-of-Thought Supervision
Xuan Gong, Senmiao Wang, Hanbo Huang, Ruoyu Sun, Shiyu Liang# (# corresponding author)
ACL 2026 Main
VCORE introduces variance-controlled optimization-based reweighting for chain-of-thought supervision, improving how reasoning traces contribute to model training.
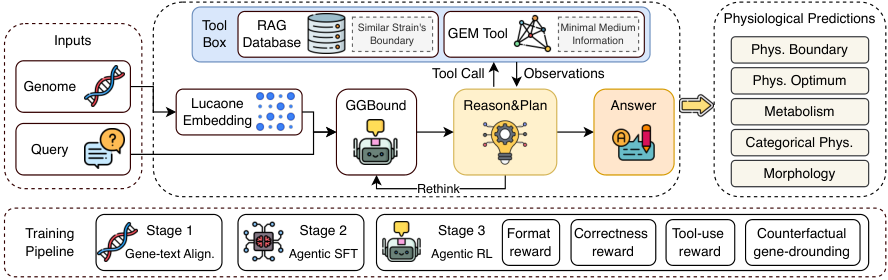
GGBound: A Genome-Grounded Agent for Microbial Life-Boundary Prediction
Hanbo Huang*, Xuan Gong*, Jing Wang*, Lei Bai, Xiang Xiao, Weishu Zhao, Shiyu Liang# (* equal contribution, # corresponding author)
Preprint 2026
GGBound presents a genome-grounded agent for predicting microbial life boundaries by combining genomic evidence with agentic reasoning.
GGBound: A Genome-Grounded Agent for Microbial Life-Boundary Prediction
Hanbo Huang*, Xuan Gong*, Jing Wang*, Lei Bai, Xiang Xiao, Weishu Zhao, Shiyu Liang# (* equal contribution, # corresponding author)
Preprint 2026
GGBound presents a genome-grounded agent for predicting microbial life boundaries by combining genomic evidence with agentic reasoning.
2025
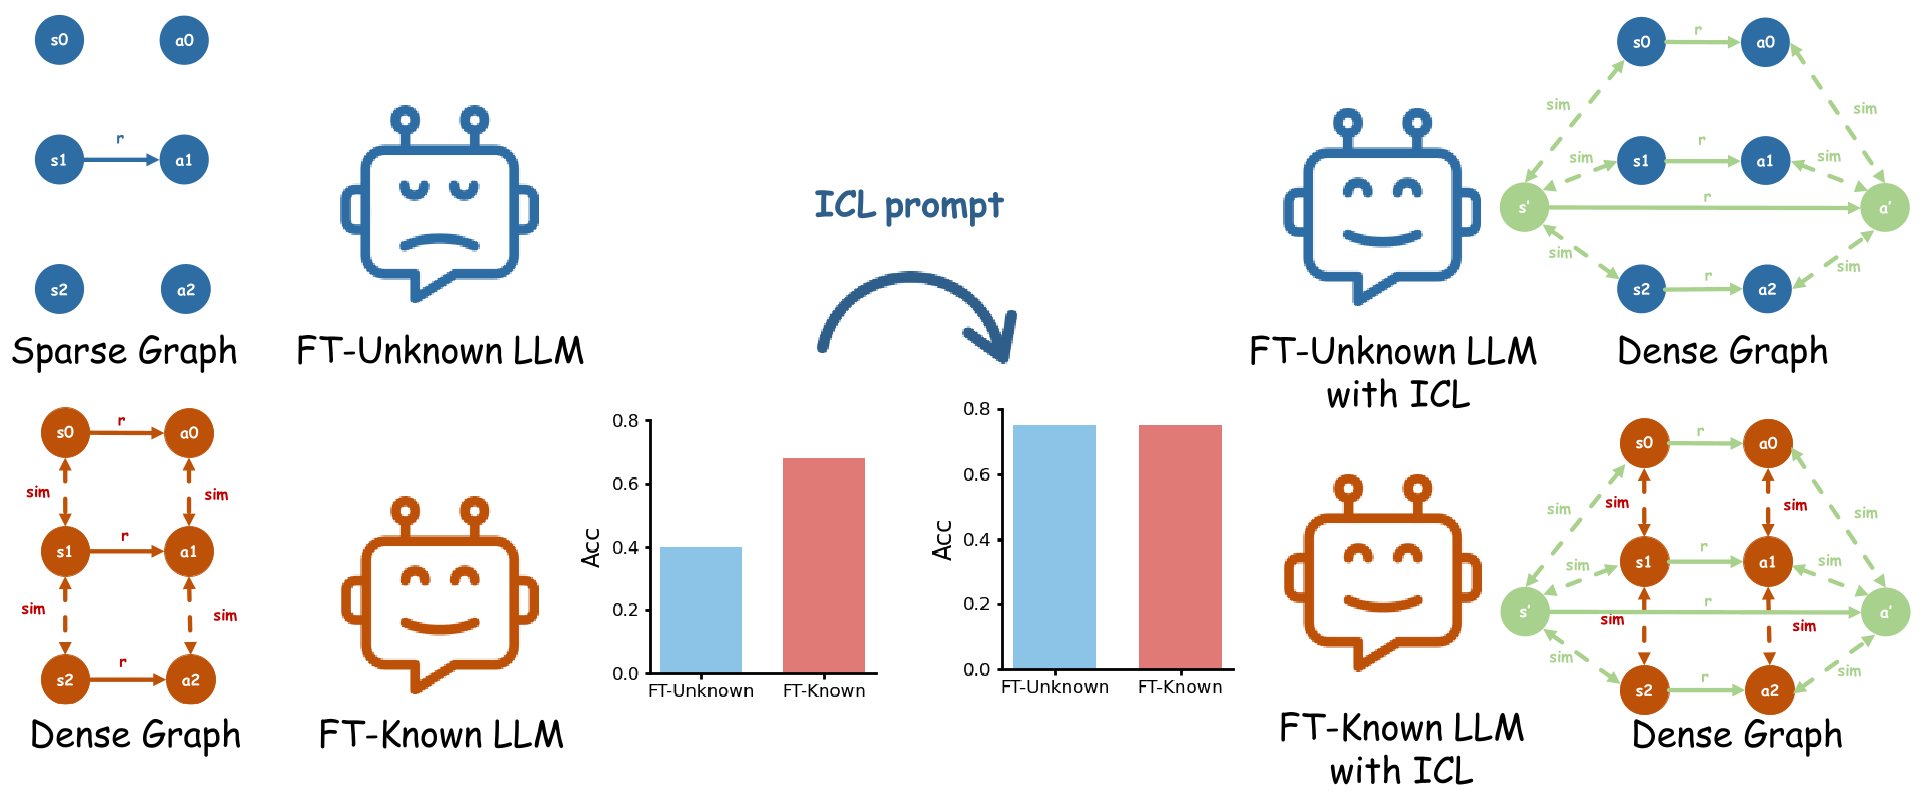
From Parameters to Prompts: Understanding and Mitigating the Factuality Gap between Fine-Tuned LLMs
Xuan Gong*, Hanbo Huang*, Yiran Zhang*, Shiyu Liang# (* equal contribution, # corresponding author)
ICASSP 2026
We revisit how supervised fine-tuning affects factual knowledge in LLMs, revealing a factuality gap between known and unknown knowledge. This gap can be mitigated at inference via in-context learning (ICL) or out-of-distribution prompts. Our theoretical and empirical results show that test-time prompts can overshadow fine-tuning data, suggesting ICL can compensate for poor fine-tuning and should be considered in evaluating fine-tuning strategies.
From Parameters to Prompts: Understanding and Mitigating the Factuality Gap between Fine-Tuned LLMs
Xuan Gong*, Hanbo Huang*, Yiran Zhang*, Shiyu Liang# (* equal contribution, # corresponding author)
ICASSP 2026
We revisit how supervised fine-tuning affects factual knowledge in LLMs, revealing a factuality gap between known and unknown knowledge. This gap can be mitigated at inference via in-context learning (ICL) or out-of-distribution prompts. Our theoretical and empirical results show that test-time prompts can overshadow fine-tuning data, suggesting ICL can compensate for poor fine-tuning and should be considered in evaluating fine-tuning strategies.
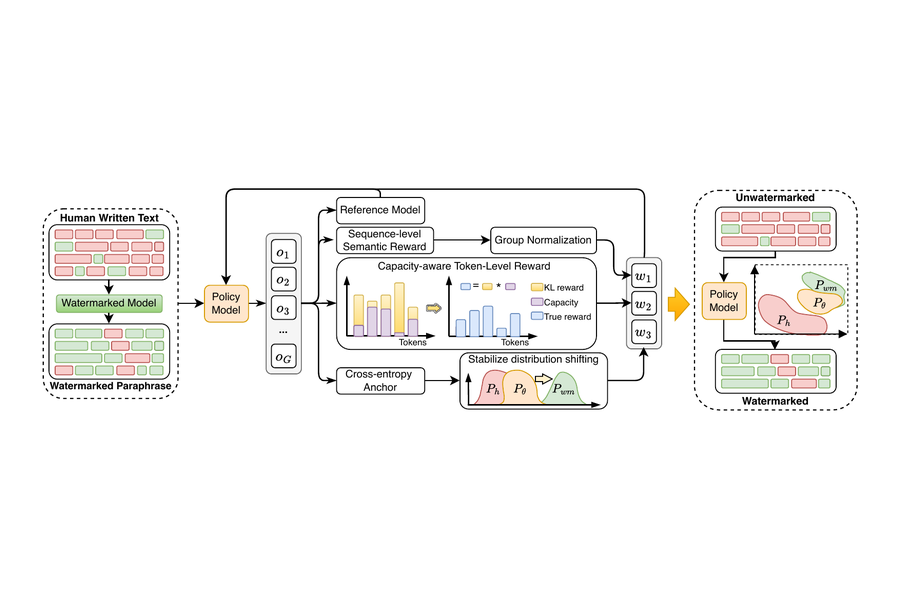
RLSpoofer: A Sample-Efficient Black-Box Spoofing Attack for Stress-Testing LLM Watermarks
Hanbo Huang, Xuan Gong, Yiran Zhang, Hao Zheng, Wenbin Dai, Jieren Kuang, Shiyu Liang# (# corresponding author)
Trustworthy AI for Good (AI4GOOD) Workshop @ ICML 2026
This workshop paper studies sample-efficient black-box spoofing attacks for stress-testing the robustness of LLM watermarks.
RLSpoofer: A Sample-Efficient Black-Box Spoofing Attack for Stress-Testing LLM Watermarks
Hanbo Huang, Xuan Gong, Yiran Zhang, Hao Zheng, Wenbin Dai, Jieren Kuang, Shiyu Liang# (# corresponding author)
Trustworthy AI for Good (AI4GOOD) Workshop @ ICML 2026
This workshop paper studies sample-efficient black-box spoofing attacks for stress-testing the robustness of LLM watermarks.
2024
DAMRO: Dive into the Attention Mechanism of LVLM to Reduce Object Hallucination
Xuan Gong, Tianshi Ming, Xinpeng Wang, Zhihua Wei# (# corresponding author)
EMNLP 2024 Main
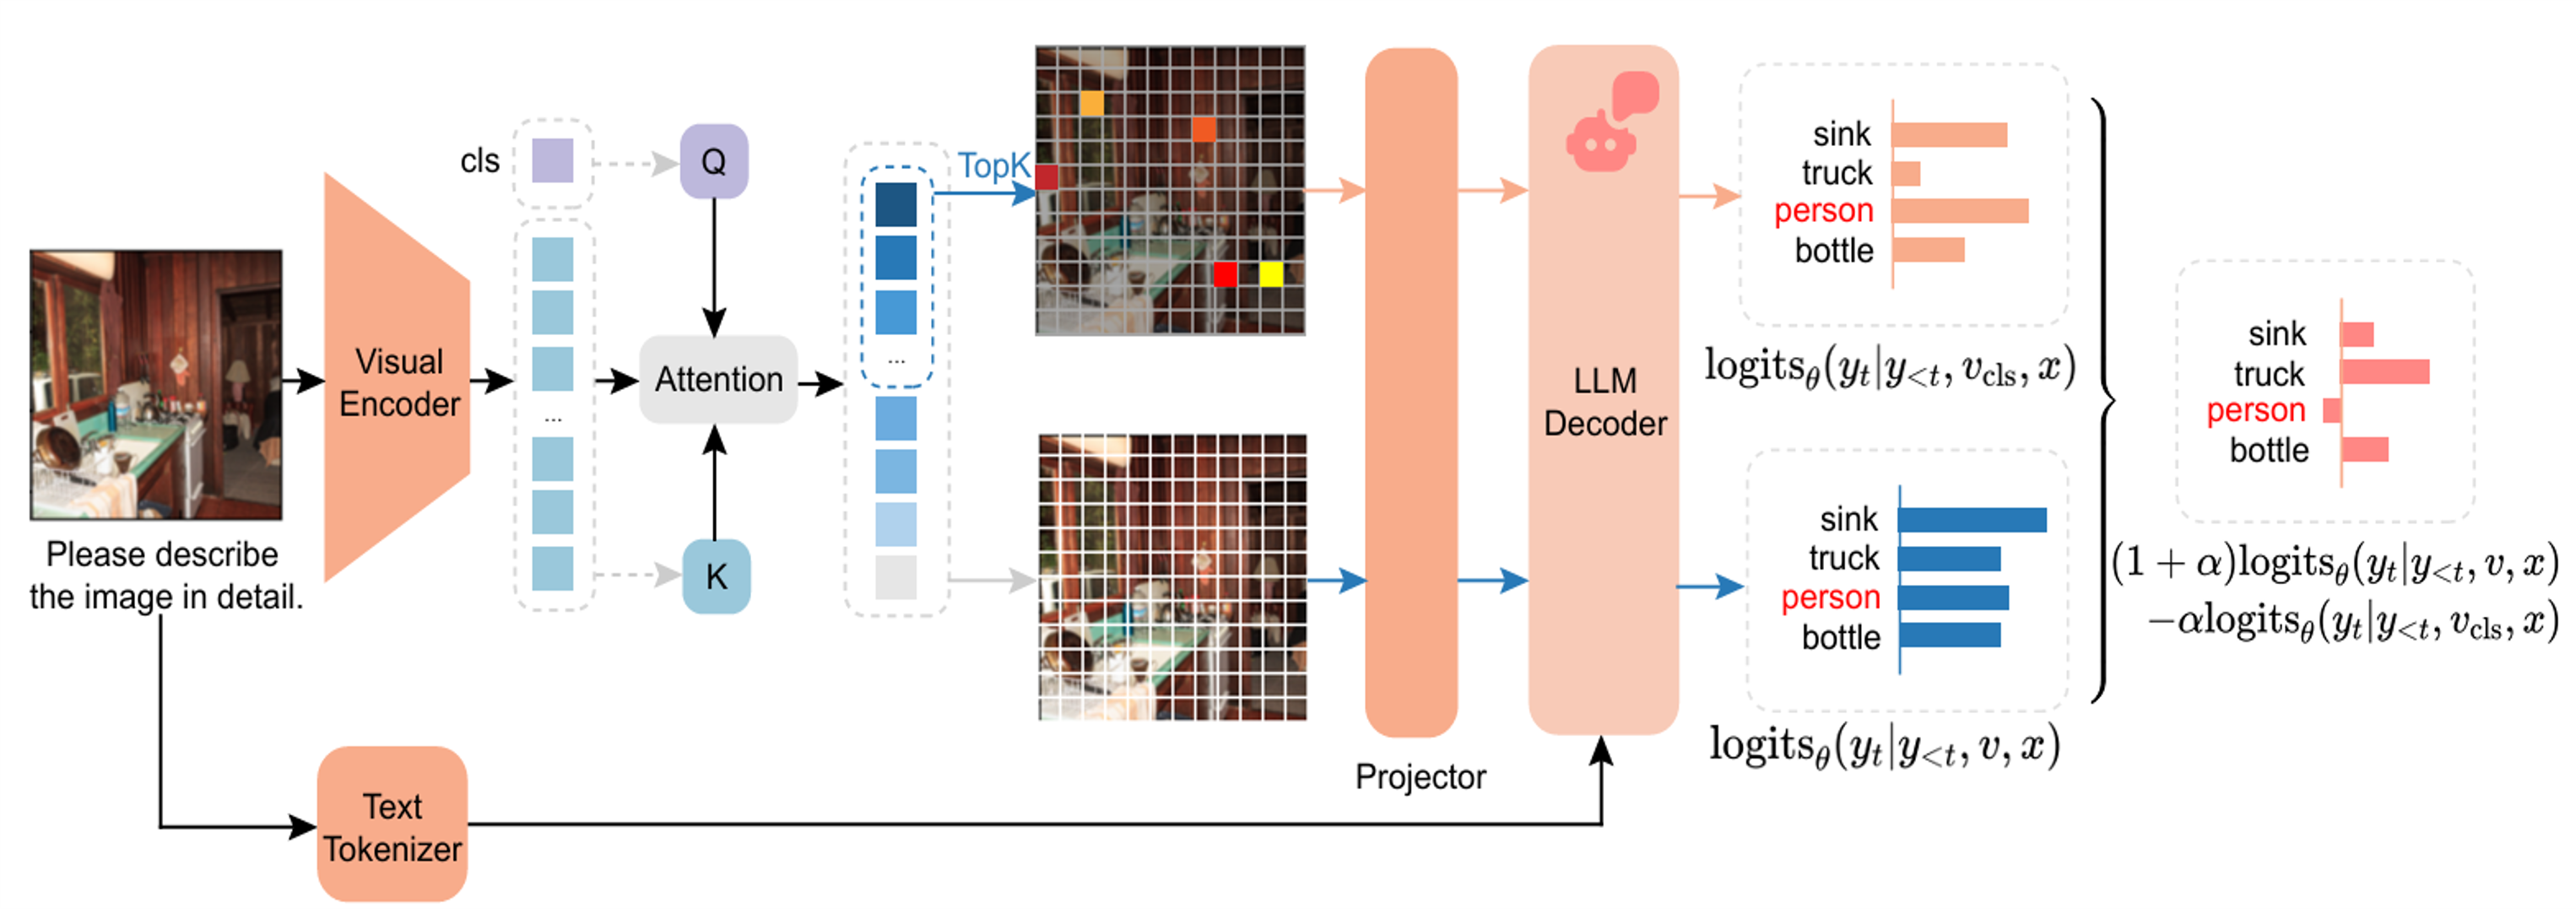
We propose DAMRO, a training-free method to reduce object hallucination in LVLMs by filtering misleading high-attention background tokens using the ViT CLS token. DAMRO significantly improves hallucination control on models like LLaVA and InstructBLIP across multiple benchmarks.
DAMRO: Dive into the Attention Mechanism of LVLM to Reduce Object Hallucination
Xuan Gong, Tianshi Ming, Xinpeng Wang, Zhihua Wei# (# corresponding author)
EMNLP 2024 Main
We propose DAMRO, a training-free method to reduce object hallucination in LVLMs by filtering misleading high-attention background tokens using the ViT CLS token. DAMRO significantly improves hallucination control on models like LLaVA and InstructBLIP across multiple benchmarks.